tutorials · ai video · comfyui
Generate AI videos with sound locally on an RTX 5070 Ti 16 GB with LTX-2.3
LTX-2.3, the open-source model from Lightricks, generates the video and the sound in a single pass: voice, sound effects, ambience. On a 16 GB gaming card, it runs locally in ComfyUI with no custom nodes, as long as you use the right version of the model and have enough RAM. Here is the exact method, with measured render times.
The tested setup
- Graphics card: NVIDIA RTX 5070 Ti, 16 GB of VRAM (Blackwell architecture).
- RAM: 64 GB. This is the non-negotiable part, see below.
- Software: ComfyUI installed through Stability Matrix 0.21 or newer. On a Blackwell card, PyTorch must be built for CUDA 12.8 or later.
- Custom nodes: none. Everything below uses ComfyUI's built-in nodes.
- Disk: plan for about 40 GB of models, ideally on an SSD.
Why 64 GB of RAM
The model weighs 29.5 GB and the text encoder 9.5 GB: together, they do not fit in 16 GB of VRAM. ComfyUI gets around this with dynamic loading: it keeps the weights in RAM and streams them to the graphics card as the computation goes.
Two practical consequences:
- VRAM stays full during the whole render, and that is normal. It is not a memory leak, nor a sign of an imminent crash.
- RAM does the heavy lifting for storage. I measured a peak of about 60 to 62 GB. With 32 GB, it does not work.
Step 1: download the three models
We use the distilled FP8 version: it generates in 8 steps instead of around thirty, and its reduced precision makes it manageable on a consumer card.
| File | Size | Hugging Face repo | ComfyUI folder |
|---|---|---|---|
ltx-2.3-22b-distilled-fp8.safetensors | 29.5 GB | Lightricks/LTX-2.3-fp8 | checkpoints |
gemma_3_12B_it_fp4_mixed.safetensors | 9.5 GB | Comfy-Org/ltx-2 | text_encoders |
ltx-2.3-spatial-upscaler-x2-1.1.safetensors | 1 GB | Lightricks/LTX-2.3 | latent_upscale_models |
With Stability Matrix: if you use the shared model folders, the checkpoint goes in Data/Models/StableDiffusion and the Gemma encoder in Data/Models/TextEncoders. The upscaler has no shared folder: put it in Data/Packages/ComfyUI/models/latent_upscale_models. Restart ComfyUI afterwards so it picks up the new files.
Step 2: set up the official template
The quickest way: download my ready-to-use workflow (distilled model, LoRA bypassed, 8 steps, CFG 1, the mouse prompt and seed) and drag the JSON file into the ComfyUI window. Put the starting image in ComfyUI's input folder, or load it in the Load Image node.
Download the workflow (JSON, 87 KB) The starting image (JPG, 44 KB)
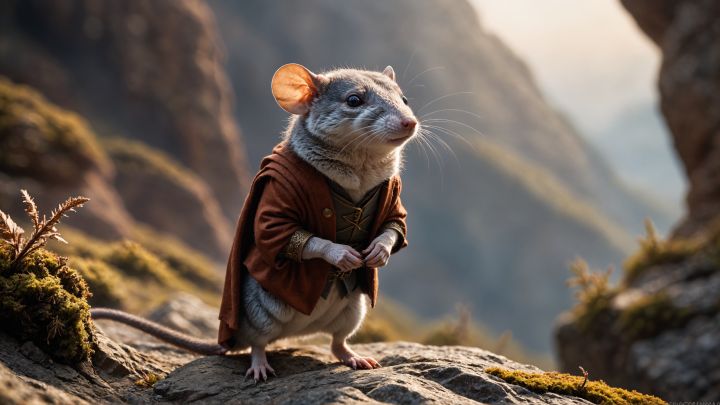
Prefer to start from scratch? ComfyUI ships an official template, you only need to adjust it:
- Open the Template Library, Video category, then LTX-2.3 I2V (image to video).
- The template is built for the dev version. In the three loaders that load the model (checkpoint, text encoder, audio VAE), replace
dev-fp8withltx-2.3-22b-distilled-fp8.safetensors. - Bypass the distilled LoRA node (right-click then Bypass, or Ctrl+B). It exists to make the dev version fast; with a model that is already distilled, it would be redundant.
- Check the sampling settings: 8 steps and CFG 1.
- Load your starting image, set the duration (in seconds) and keep 25 frames per second.
The workflow works in two stages: it first generates the video at half resolution, then upscales it ×2 directly in latent space with the upscaler, before decoding the picture and the sound. This is what makes 720p output (1280 × 704) possible without blowing up memory.
Step 3: write a prompt that works
This is the step that makes the difference between a limp clip and a scene that tells a story. The rules I kept after my tests:
- In English, even when the character speaks another language.
- A single shot, split into timed actions:
0-2s: …,2-4s: …. Plan one action every 2 to 3 seconds. - Observable verbs: “sprints”, “leaps”, “turns its head”. No intentions or abstract emotions.
- Explicit camera work: static shot, tracking shot, slow push-in. Without instructions, the model improvises.
- Lighting consistent with the image you start from: same direction, same color.
- An
Audio: …line at the end, listing the voice, the ambience and the sound effects.
The mouse prompt
Here is the exact prompt behind the video at the top of the page: ears perking up, a line spoken to the camera, a sprint, a jump between two rocks, then a heroic pose over the valley.
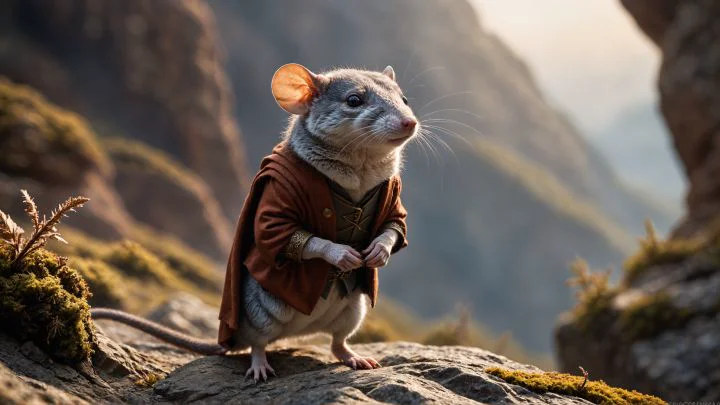
The small mouse in a rust-colored cloak stands on the rocky mountain ledge at golden hour. 0-2s: its ears snap upright and it looks sharply to the right, whiskers twitching. 2-4s: it turns its head toward the camera and says in French, in a small, excited voice: "Tu as entendu ça ? L'aventure nous appelle !" 4-6s: it drops onto all fours and sprints along the ledge, its cloak flapping behind it, small pebbles bouncing off the rock. 6-8s: it leaps across a narrow gap to the next boulder, legs fully stretched in midair, and lands with a small skid, dust puffing around its paws. 8-10s: it rises on its hind legs at the edge, chest heaving, and gazes proudly over the misty valley as the wind lifts its cloak. The camera tracks smoothly alongside the mouse at its height, then slows and settles into a low hero angle at the end. Warm golden sunlight from the right, glowing rim light on its fur, mountains softly blurred in the background. Audio: the mouse's small clear voice, rushing mountain wind, tiny rapid footsteps on stone, pebbles clattering, a soft thud on landing, an eagle cry in the distance.Making a character speak
LTX-2.3 can make a character speak, in French as well as in English, with decent lip sync, provided you respect three conditions:
- the line is in quotes;
- it fits in 6 to 8 words per 2 seconds of speech;
- the character is still and facing the camera while speaking. A line delivered mid-run gives a rough mouth.
Close-up of the small mouse in a rust-colored cloak standing on the rocky mountain ledge. It turns its head toward the camera, its ears perk up, and it speaks in French with a small, determined voice: "La montagne est haute, mais mon courage aussi." Its mouth moves clearly with each word, whiskers twitching. A light breeze ruffles its fur and cloak. Warm golden hour light, misty mountains softly blurred in the background. Slow push-in toward its face, shallow depth of field. Audio: the mouse's small clear voice, soft wind, faint distant bird calls.The template to reuse
Replace the brackets, keep the structure. For an English line, simply write says: instead of says in French:.
The [subject exactly as seen in the image] stands [where], [time of day].
0-2s: it [one observable action].
2-4s: it turns toward the camera and says in French: "[6 to 8 words]"
4-6s: it [one observable action].
6-8s: it [one observable action].
The camera [explicit move: static shot / slow push-in / tracks alongside].
[Light matching the image: direction, color, mood].
Audio: [voice], [ambience], [sound effects].
The trap: never use negations
With CFG set to 1, the model cannot tell “show this” from “do not show this”: every word in the prompt adds its concept to the picture. Writing no text therefore makes text appear. Always describe what you want to see (“a clear blue sky”) rather than what you do not want (“no clouds”).
Measured render times
Measured at 720p and 25 frames per second, on the setup above:
| Video length | Render time | Peak RAM |
|---|---|---|
| 5 seconds | ≈ 3 min | ≈ 60 to 62 GB |
| 10 seconds | ≈ 4 min 20 s | |
| 15 seconds | ≈ 5 min 50 s |
- The first render after starting ComfyUI takes about 1 extra minute, the time it takes to load the models into RAM.
- Some of these measurements were made with a slightly heavier variant of the same model. With the official model, expect the same times or slightly less.
- Render time does not double when the length doubles: a good part of the cost is fixed (prompt encoding, loading, decoding).
What did not work: 12 fps and interpolation
To save time, I tried generating at 12 frames per second and then interpolating to 24 with RIFE. Avoid it: hands become smeared and blurry as soon as the character moves quickly.
You might think this is the same thing as DLSS Frame Generation in games. It is not, for two reasons:
- In a game, the engine provides the exact motion vectors of every pixel. The AI has nothing to guess about where objects are going. RIFE has to estimate motion from just two images.
- Frame Generation starts from around 60 fps: 16 ms pass between two frames and almost nothing moves. At 12 fps, 83 ms pass, and a paw or a hand has time to change shape completely. That is exactly where the estimation breaks.
Bottom line: generate directly at 25 fps. The extra render time is real, but the result is clean.
Going further
- LTX-2.5, released in August 2026, also advertises 16 GB of VRAM, but ComfyUI recommends 32 GB. Try it with caution on a 16 GB card.
- NVFP4 versions of LTX-2.3: Blackwell cards (RTX 50 series) natively accelerate FP4 computation. This is the next lead for cutting render times on this kind of card.
FAQ
Does LTX-2.3 really run with 16 GB of VRAM?
Yes, in its distilled FP8 version, thanks to ComfyUI's dynamic loading which keeps the model in RAM. VRAM stays full throughout the render: that is the expected behavior, not a problem.
Is 32 GB of RAM enough?
No. The model and the text encoder alone weigh almost 40 GB, and I measured a RAM peak around 60 GB. You need 64 GB.
Is the sound added afterwards?
No, that is the whole point of LTX-2.3: picture and sound are generated together, in the same pass. Sound effects land at the right moment, and the mouth follows the spoken line.
Can I start from text instead of an image?
Yes, the Template Library also offers a text-to-video (T2V) template, set up the same way. Starting from an image gives you much more control over the character and the setting, though.